Prompt-engineering research prototype

What they said.What they filed.What the math says.

Specialist models find candidate issues. Python recomputes every number. The full filing gets a second look. Exact quotes are validated before a human decides.

See benchmark

12 controlled cases · 13 findings · live model comparison

01

Models interpret. Code calculates.

Every explanation must
survive validation.

Specific filing evidence + direct connection + exact quote + numerical reconciliation = explained. Anything less remains unresolved.

01Ingest & align
02Specialist calls
03Aggregate & dedupe
04Code calculation
05Filing retrieval
06Second pass & validate
07Analyst review
08Human sign-off
02

Judge Demo mode | three decisive cases

JUDGE DEMO

Northstar Mobility

Q2 FY2026 | controlled fictional demonstration

Ready: unresolved + explained + within tolerance0 / 3
Evidence trace Case 1 | Numerical discrepancy

Management statement

"Organic segment revenue grew 23 percent year over year, reflecting broad-based demand."
SourceQ2 earnings call | prepared remarks
checked against
Filed sourceNote 3 | Segment table
No explanation quote submitted | remains UNRESOLVED
SAME EVIDENCE | TWO METHODSExpected: unresolved
LIVE SINGLE PROMPTCORRECT
unresolved
"To resolve this inconsistency, it would be necessary to review the calculation of organic growth in more detail."
FULL FINTRACECORRECT
unresolved

No quantified filing disclosure bridges the 10.27 percentage-point gap.

No filing disclosure quantifies an acquisition, currency, divestiture, policy, or segment effect that reconciles the 10.27 percentage-point difference.
Expandable evidence chain FT-001
01Management claim+

Organic segment revenue grew 23 percent year over year, reflecting broad-based demand.

02Filed values+

Segment note p. 18: current revenue $124m; prior revenue $110m. MD&A p. 24: acquired operations are excluded from organic growth, with no quantified effect.

03Python calculation+

(124 - 110) / 110 x 100

04Computed vs claimed+

12.73% vs 23.00%; difference 10.27 pp

05Filing passages searched+

Segment note p. 18: current revenue $124m; prior revenue $110m. | MD&A p. 24: acquired operations are excluded from organic growth, with no quantified effect.

06Candidate explanation+

No candidate passage numerically reconciles the difference.

07Second-pass decision+

No filing disclosure quantifies an acquisition, currency, divestiture, policy, or segment effect that reconciles the 10.27 percentage-point difference.

08Quote validation+

No explanation quote submitted | remains UNRESOLVED

09Human decision+

Pending. The system does not make the final judgment.

08
Human judgment stays in the loop

FinTrace describes inconsistencies. An analyst decides what they mean.

03

Measured controlled benchmark

Same evidence. Different controls.

12 controlled fictional cases containing 13 independently evaluated findings. Both headline runs used llama-3.3-70b-versatile at temperature 0.0.

+3 correct findings+23.1 percentage points
Live Single Prompt76.9%10 / 13 correct
Live Full FinTrace100.0%13 / 13 correct
RECORDED FULL-PIPELINE RUNAudit the result, not just the headline.
Token usage and estimated cost were not persisted for this run.
Modelllama-3.3-70b-versatile
Temperature0.0
Timestamp2026-08-10 UTC
LLM calls5 batched calls
Logged retries7 HTTP 429 retries
Benchmark scope12 cases | 13 findings
Classification accuracy
Single76.9%
FinTrace100.0%
Unsupported-explanation count
Single1
FinTrace0
Unresolved-item accuracy
Single80.0%
FinTrace100.0%
False-positive count
Single1
FinTrace0
Live comparison | separately graded raw outputs suite v1.0.0
WorkflowCorrectClassification accuracyUnsupported explanationsUnresolved-item accuracyFalse positives
live single prompt10/1376.9%14/5 (80.0%)1
live full FinTrace13/13100.0%05/5 (100.0%)0

Reproducible formula: classification accuracy = correct classifications / 13 findings x 100. Integrity checks verified 24 percentage calculations before this artifact was generated. Results are limited to this controlled fictional benchmark and are not a claim of general model performance.

Why older results showed 55.6, 61.5%, and 74.9

55.6 and 74.9 are composite control-index points from the deterministic ablation. The earlier 61.5% was also produced by that simulated ablation, not a live single-prompt call. The current live single-prompt measurement is 76.9%. Historical formula: mean(classification accuracy, 100 - false-positive rate, 100 - unsupported-explanation rate, numeric reconciliation accuracy, citation quote validity, unresolved-item accuracy).

04

Why not a single prompt?

More steps.
Better evidence.

The comparison is not about adding complexity for its own sake. Each FinTrace stage owns one check that a broad prompt can skip: calculation, retrieval, relevance, quotation, reconciliation, or human judgment.

LIVE SINGLE PROMPT

Can identify a plausible explanation.

In this run it missed one exact acquisition explanation, flagged one within-tolerance case, and accepted one adjustment that did not reconcile numerically.

FINTRACE

Adds explicit gates.

  • Requires deterministic calculation
  • Retrieves filing evidence
  • Requires direct relevance
  • Validates the quotation
  • Preserves unresolved cases
  • Requires human review

This comparison describes one recorded run on a controlled fictional benchmark. It does not claim that every multi-step workflow is always better.

05

Try deterministic calculation

Change the values.
Watch the gap move.

This browser-only calculator uses the same growth formula as the controlled demonstration. No model is called and no values leave the page.

PYTHON-EQUIVALENT FORMULA(current - prior) / prior x 100
Calculated growth12.73%
Claim minus calculation10.27 pp

Outside the 0.50 percentage-point demonstration tolerance. A filing explanation would need to reconcile this gap.

06

Prompt Inspector

Inspect every model contract.

Judges can see the version, instruction, input contract, expected schema, and sample output. Secrets never enter this interface.

ACTIVE LLM CALLS4 specialists -> second passFive batched calls in the benchmark; versioned prompts and schema-validated outputs
->
DETERMINISTIC CODEAggregation + Python calculation + quote validationAggregator contract is defined but not wired as an LLM call
LLM CALL
Stagerevenue
Modelprovider selected / local deterministic adapter
Temperature0.0
Prompt version1.0.0

Purpose

Check revenue, growth, and segment claims against filed values.

System instruction

You are a financial analyst reviewing only revenue, growth, demand, and segment claims. Compare transcript statements with the supplied filing. Report only a specific inconsistency or a claim the filing should substantiate but does not. Do not infer intent and do not treat your arithmetic as authoritative; deterministic code performs final calculations. Return ONLY valid JSON: {"findings":[{"finding_id":"string","claim_quote":"string","filed_data_reference":"string","inconsistency":"string","severity":"critical|high|medium|low","rationale":"string"}]}. If nothing is found return {"findings":[]}.

Input

{
  "claims": "array",
  "filing": "object"
}

Structured output

{
  "findings": []
}

Expected JSON schema

{
  "type": "object",
  "required": [
    "findings"
  ],
  "properties": {
    "findings": {
      "type": "array",
      "items": {
        "type": "object",
        "required": [
          "finding_id",
          "claim_quote",
          "filed_data_reference",
          "inconsistency",
          "severity",
          "rationale"
        ],
        "properties": {
          "finding_id": {
            "type": "string"
          },
          "claim_quote": {
            "type": "string"
          },
          "filed_data_reference": {
            "type": "string"
          },
          "inconsistency": {
            "type": "string"
          },
          "severity": {
            "type": "string",
            "enum": [
              "critical",
              "high",
              "medium",
              "low"
            ]
          },
          "rationale": {
            "type": "string"
          }
        }
      }
    }
  }
}
VALIDATION RESULTPASS - structured output is checked against the versioned JSON schema
07

System architecture

The complete evidence chain.

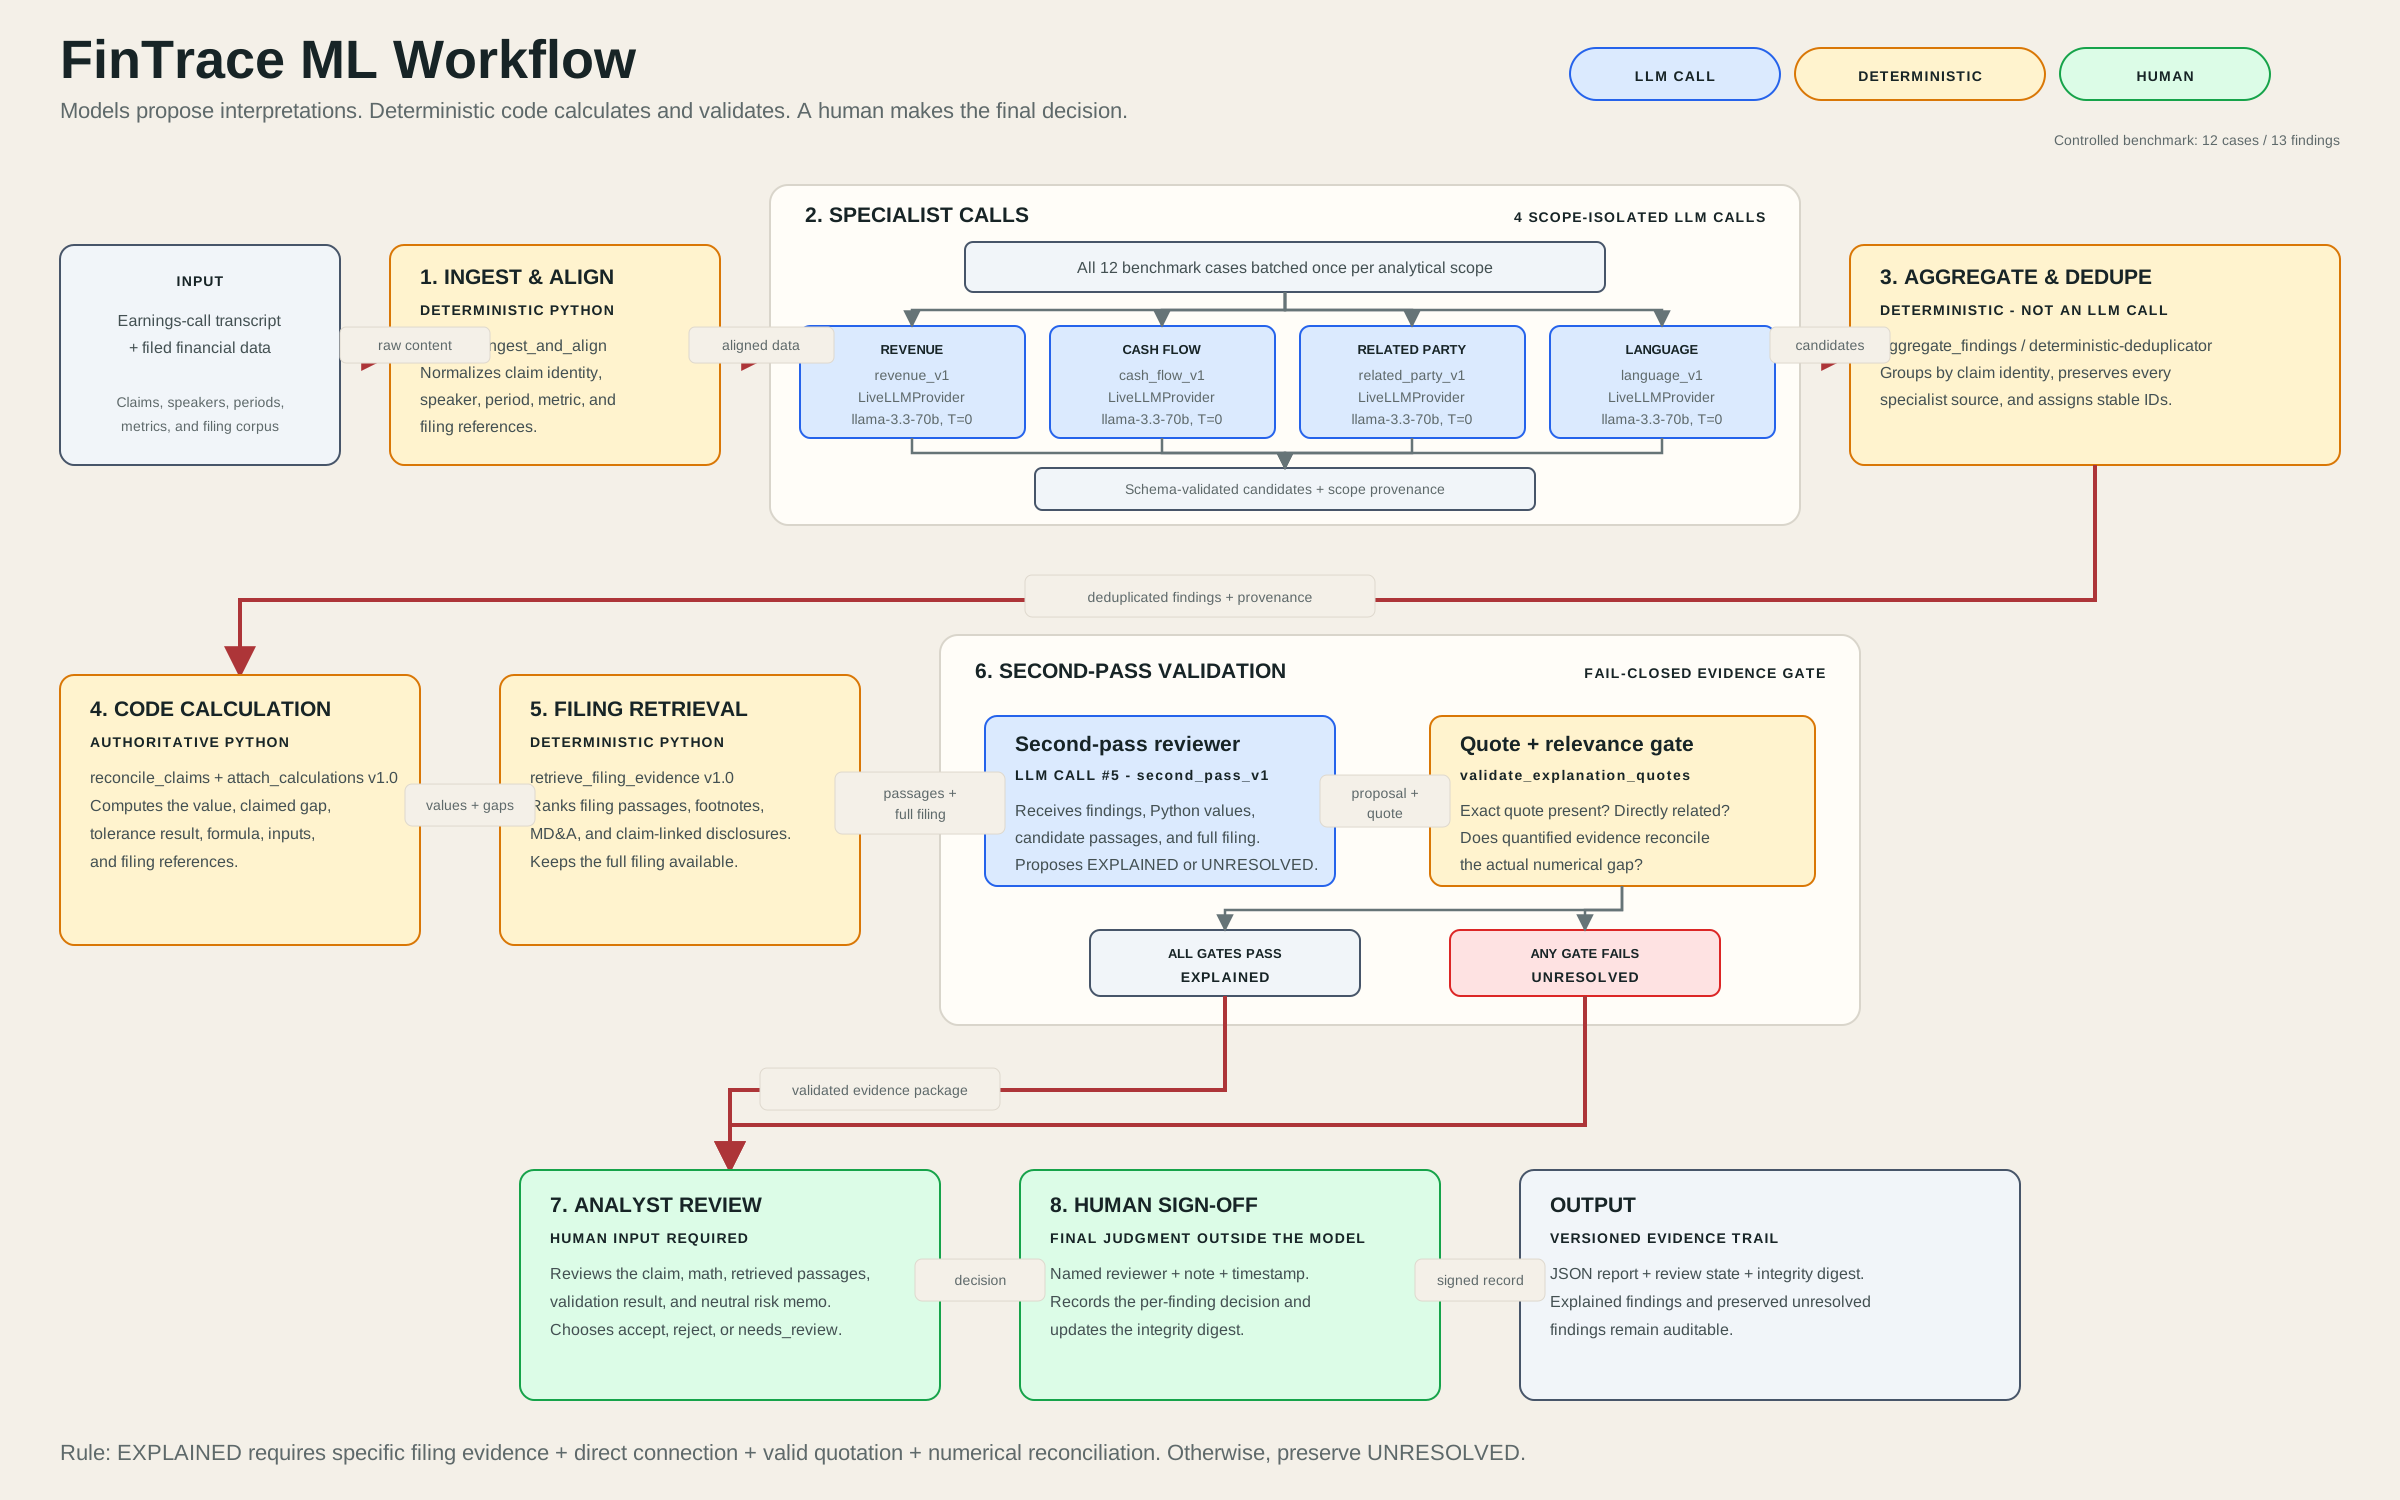
Follow every handoff from raw transcript and filing data to scoped model calls, authoritative Python calculations, fail-closed validation, and named human sign-off.

Read each role in detail
FinTrace eight-stage system architecture separating LLM calls, deterministic Python, evidence validation, analyst review, and human sign-off
LLM proposesPython calculates and validatesHuman decidesOpen full-size PNG
08

Where FinTrace refuses to guess

Unresolved is a feature.

01

Insufficient filing data

The filing names an effect but does not quantify it.

RESULT: UNRESOLVED
02

Plausible but unsupported

The explanation sounds reasonable but is absent from the filing.

RESULT: UNRESOLVED
03

Quote cannot be validated

A proposed quotation is not found in the supplied corpus.

RESULT: UNRESOLVED
04

Numerical gap remains

The disclosure exists but does not bridge computed and claimed values.

RESULT: UNRESOLVED
05

Contradictory passages

Conflicting evidence is preserved for a human instead of resolved by assumption.

RESULT: UNRESOLVED